Running Qwen 3.5 Locally on a Single GPU: Complete Setup Guide
Alibaba just released Qwen 3.5, and it's genuinely impressive. This newest model in Alibaba's lineup builds on everything that made previous Qwen versions strong—solid reasoning, solid coding, solid multimodal capabilities. The real standout? You can actually run it locally on consumer-grade hardware now, thanks to aggressive quantization.
Independent benchmarks show the Qwen 3.5-397B-A17B model scoring exceptionally high on widely-used tests like LiveCodeBench and AIME26. It consistently outperforms top-tier models like GPT-5.2 and Claude Opus 4.5 across most evaluation categories, while delivering significantly better throughput than earlier Qwen generations.
Table of Contents
Hardware and Software Requirements for Qwen 3.5
Before spinning up Qwen 3.5 locally, you need to ensure your setup meets both the hardware and software requirements for smooth inference. This guide uses an NVIDIA H200 GPU with 141GB VRAM paired with 240GB system RAM, providing enough memory to run Qwen 3.5's MXFP4_MOE variant efficiently with MoE offloading enabled.
To give you a sense of scale: Unsloth's dynamic 4-bit quantization (UD-Q4_K_XL algorithm) consumes roughly 214GB of disk space. You can install it directly on a 256GB M.2 Ultra SSD, and it also runs well on a 24GB GPU with 256GB RAM, achieving over 25 tokens per second with MoE offloading active. Smaller 3-bit quantizations fit within 192GB RAM, while higher-precision 8-bit versions might need up to 512GB of combined VRAM and RAM.
The general rule: your total VRAM plus RAM should roughly match the size of the quantized model you're downloading. Otherwise, llama.cpp will spill onto your SSD, and inference speed drops noticeably.
On the software side, you'll need the latest NVIDIA GPU drivers and a recent CUDA Toolkit version to ensure full compatibility with llama.cpp and CUDA-accelerated inference.
How to Run Qwen 3.5 Locally
Once you've confirmed the prerequisites are met, here's the step-by-step process to get Qwen 3.5 running on your machine:
1. Setting Up Your Local Environment
To run Qwen 3.5 locally, you need access to a machine with a powerful GPU. Since most laptops and desktops lack sufficient VRAM or memory for these massive models, we'll use a cloud-based GPU virtual machine.
This guide uses Hyperbolic for private model hosting. You can also pick RunPod, Vast.ai, or any other GPU cloud platform you prefer. We chose Hyperbolic because it currently offers some of the most cost-effective GPU instances available.
Start by spinning up a fresh instance with a single H200 GPU.
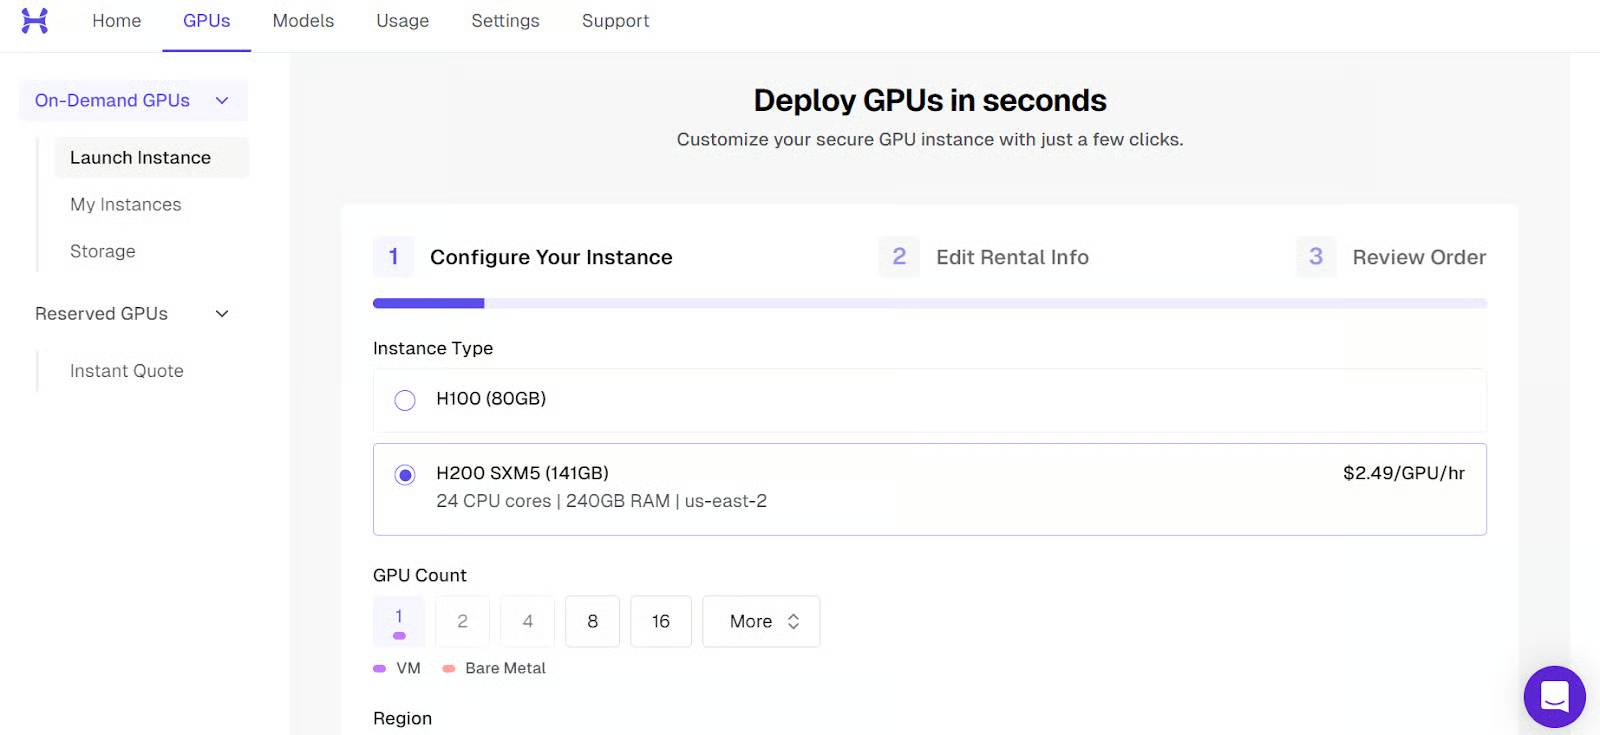
Once the machine boots, you'll see a public IP address and the SSH command needed to connect from your local terminal.
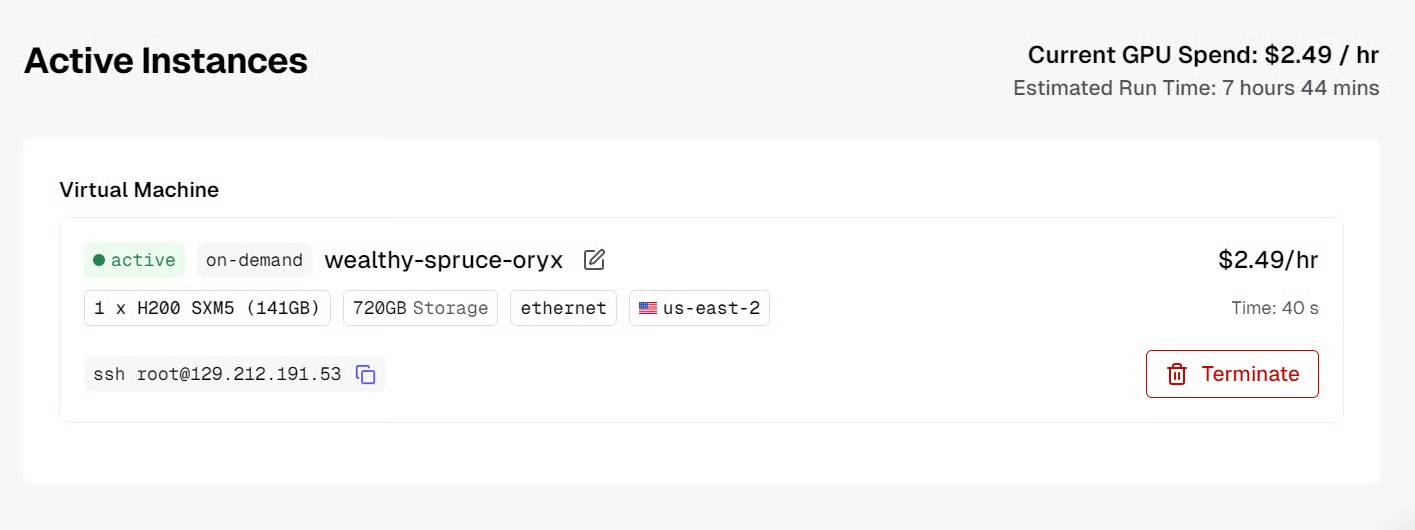
Before connecting, make sure you've set up SSH locally and added your public SSH key when creating the virtual machine.
Once the instance is ready, connect via SSH with port forwarding. This is crucial because we want to access the llama.cpp inference server locally through port 8080:
ssh -L 8080:localhost:8080 root@129.212.191.53On first connection, type yes to confirm, then authenticate with your SSH key.
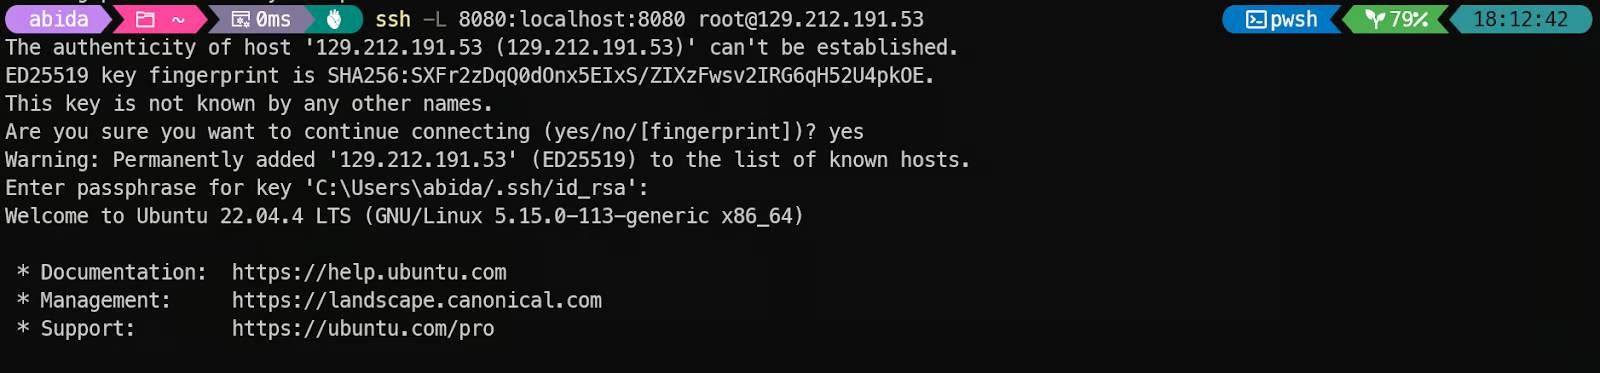
After login, verify the GPU is recognized correctly:
nvidia-smiYou should see the NVIDIA H200 listed in the output.
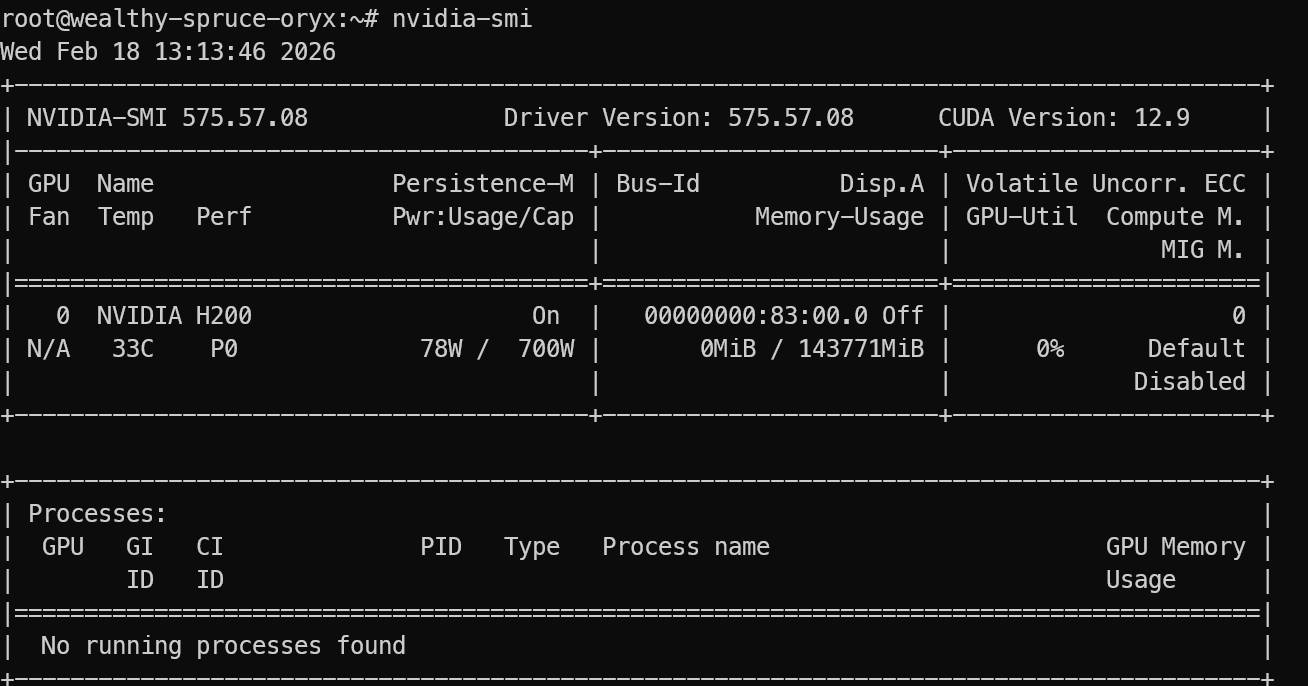
Finally, install the required Linux packages for downloading, compiling, and running llama.cpp:
sudo apt update
sudo apt install pciutils build-essential cmake curl libcurl4-openssl-dev -y
Once that finishes, your environment is ready for llama.cpp installation and running Qwen 3.5 locally.
2. Installing llama.cpp with CUDA Support
llama.cpp is an open-source C and C++ inference tool that lets you run large language models locally with minimal setup, supporting both CPU and GPU acceleration.
First, clone the llama.cpp repository:
git clone https://github.com/ggml-org/llama.cppNext, configure the build with CUDA support using CMake. We enable CUDA with -DGGML_CUDA=ON and set the CUDA architecture to 90a because we're using an NVIDIA H200 (Hopper class). This ensures the build generates GPU code optimized for Hopper's specific features.
cmake llama.cpp -B llama.cpp/build \\
  -DGGML_CUDA=ON \\
  -DCMAKE_BUILD_TYPE=Release \\
  -DCMAKE_CUDA_ARCHITECTURES="90a"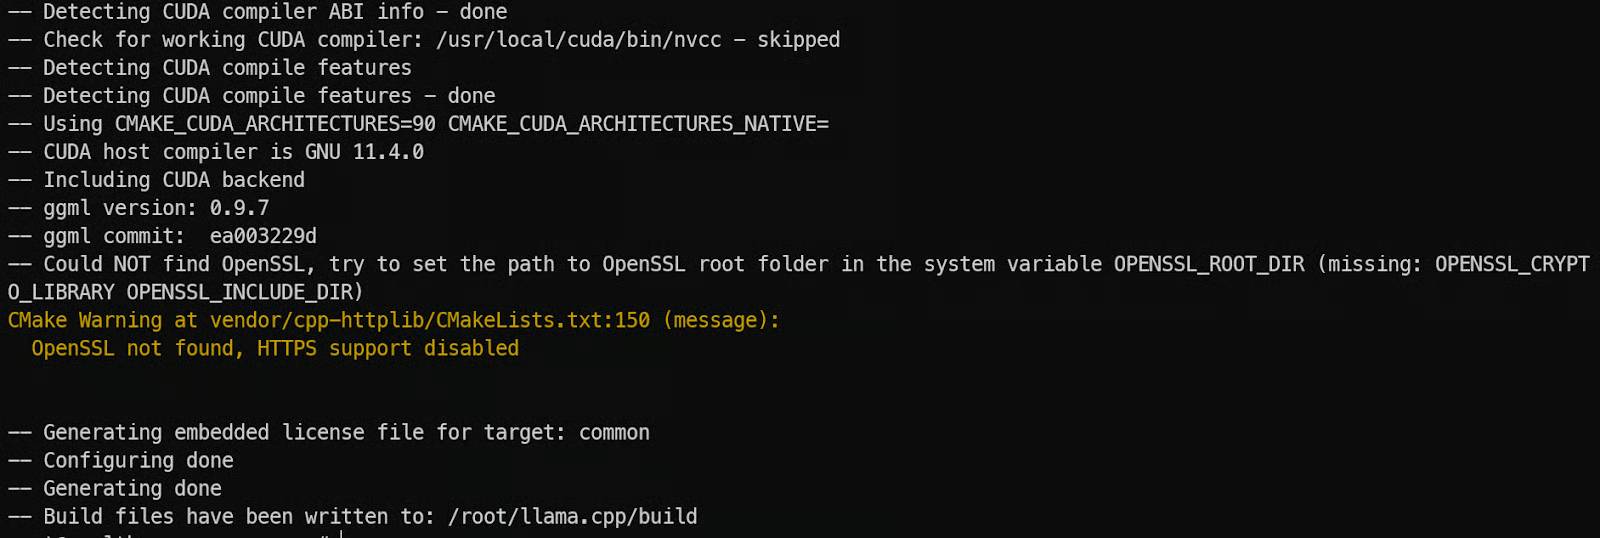
Now compile the server binary. llama-server is a built-in REST server that lets you expose llama.cpp as an API endpoint:
cmake --build llama.cpp/build --config Release -j --clean-first --target llama-server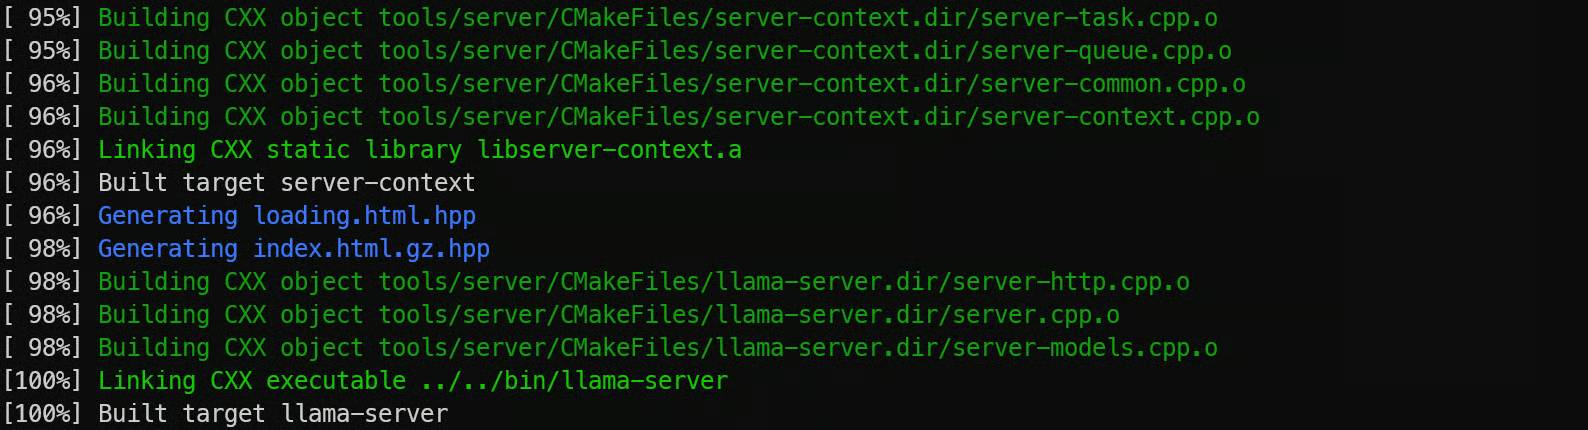
Finally, copy the compiled binaries to the main directory for easy execution:
cp llama.cpp/build/bin/llama-* llama.cpp3. Downloading Qwen 3.5 Model Weights
Now that llama.cpp is installed, the next step is fetching the actual Qwen 3.5 model weights in GGUF format. These files are huge, so using the Hugging Face CLI is the most reliable way to download them directly onto your GPU machine.
Python needs to be installed first since Hugging Face's download and authentication tools are distributed as Python packages. Even though llama.cpp itself is written in C++, Python makes managing downloads and model transfers much easier.
Start by installing pip:
sudo apt install python3-pipNext, install the Hugging Face Hub client along with performance utilities. hf_transfer and hf-xet significantly speed up downloads, which matters when pulling hundreds of gigabytes of model files:
pip -q install -U huggingface_hub hf-xet
pip -q install -U hf_transfer
Now, download the Qwen 3.5 model from Hugging Face. In this guide, we'll grab just the MXFP4_MOE variant, optimized for efficient MoE inference:
hf download unsloth/Qwen3.5-397B-A17B-GGUF \\
   --local-dir models/Qwen3.5 \\
   --include "*MXFP4_MOE*"
Once the download completes, the model files are stored in models/Qwen3.5, ready to be loaded into llama.cpp for local inference.
4. Launching Qwen 3.5 on a Single GPU
Now we can fire up Qwen 3.5 using llama-server. This gives us an OpenAI-compatible API endpoint we can call from local tools and applications.
Optimize the server for single-GPU setups by doing three key things. First, enable the --fit flag so llama.cpp automatically balances the model between GPU VRAM and system RAM instead of throwing an error when it doesn't all fit in VRAM.
Second, use a larger context window with --ctx-size 16384 so the server handles longer prompts. Third, enable the --jinja flag and pass --chat-template-kwargs to control chat formatting and disable thinking mode for faster, more direct responses.
Run the server with:
./llama.cpp/llama-server \\
    --model models/Qwen3.5/MXFP4_MOE/Qwen3.5-397B-A17B-MXFP4_MOE-00001-of-00006.gguf \\
    --alias "Qwen3.5" \\
  --host 0.0.0.0 \\
  --port 8080 \\
  --fit on \\
  --jinja \\
   --ctx-size 16384 \\
   --temp 0.7 \\
   --top-p 0.8 \\
   --top-k 20 \\
   --min-p 0.00 \\
   --chat-template-kwargs "{\\"enable_thinking\\": false}"
As the model loads, you'll see it using both GPU VRAM and system memory—this is normal for a large MoE model.
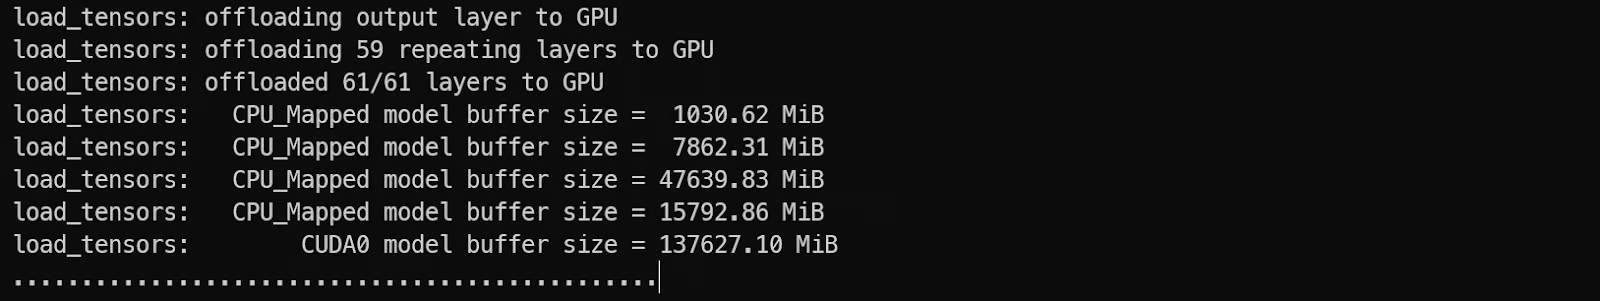
Once loading finishes, the server is accessible at:
- 0.0.0.0:8080 on the virtual machine
- http://127.0.0.1:8080 on your local machine after SSH port forwarding
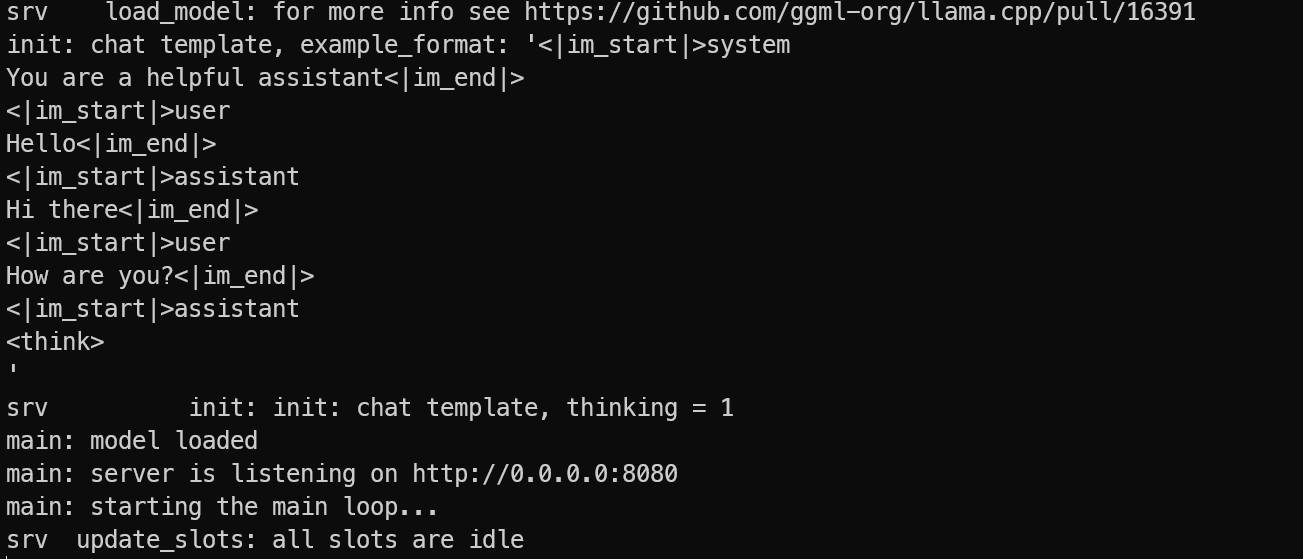
Leave the server running. On your local machine, open a new terminal window and reconnect with SSH port forwarding:
ssh -L 8080:localhost:8080 root@129.212.191.53Then verify the server by listing available models:
curl -s http://127.0.0.1:8080/v1/modelsIf you see Qwen 3.5 in the response, your server is running correctly and you're ready to call it from OpenAI SDK and local applications.

5. Testing Qwen 3.5 with OpenAI SDK
Now that the Qwen 3.5 inference server is running, the next step is confirming it works correctly with real client applications. One of llama.cpp's biggest wins is that llama-server provides an OpenAI-compatible API, meaning you can use the official OpenAI SDK without changing your code structure.
First, install the Python OpenAI package on your local machine (or inside the VM if you prefer):
pip install openaiNow, run a simple test script. This script connects to your locally-forwarded endpoint at http://127.0.0.1:8080/v1 instead of OpenAI's cloud servers.
python3 - <<'PY'
from openai import OpenAI

client = OpenAI(
    base_url="http://127.0.0.1:8080/v1",
    api_key="sk-no-key-required"
)

response = client.chat.completions.create(
    model="Qwen3.5",
    messages=[
        {"role": "user", "content": "Write one sentence about AI agents."}
    ]
)

print(response.choices[0].message.content)
PY
A few important details here:
- base_url points to your local Qwen 3.5 server, not OpenAI's API.
- api_key is still required by the SDK, but llama.cpp doesn't enforce authentication, so any placeholder value works.
- model="Qwen3.5" matches the alias we set when starting the server.
If everything is configured correctly, you'll get a quick, clean response from the model.
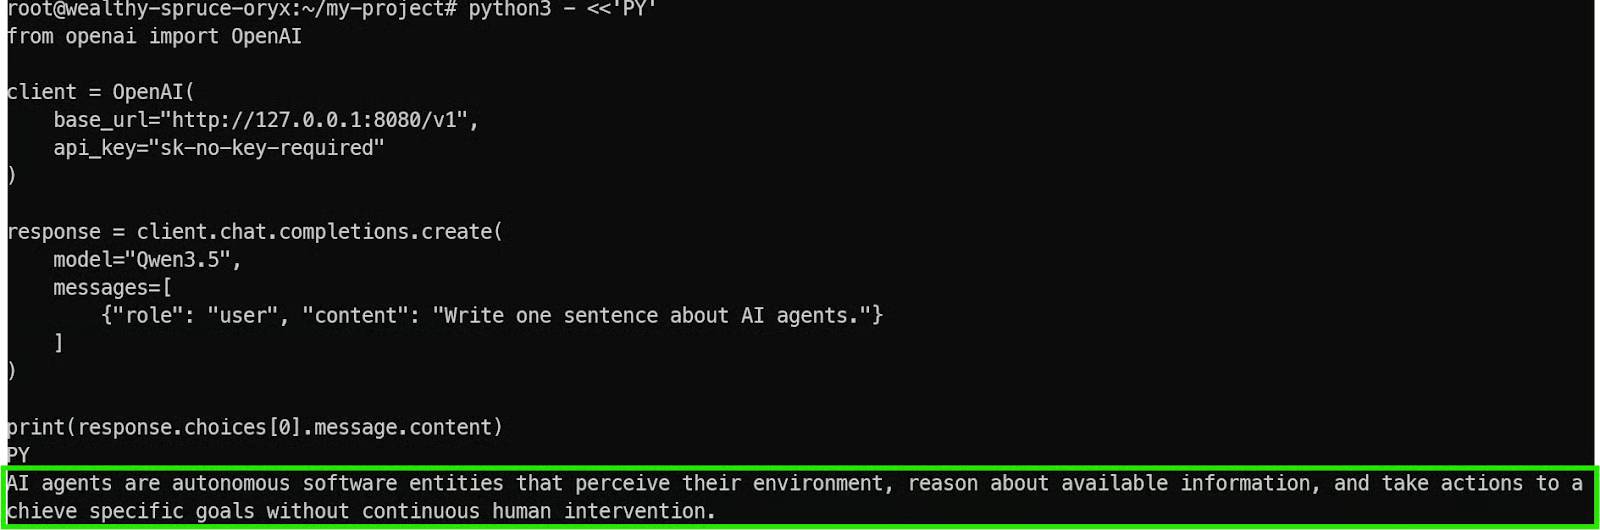
This confirms that:
- Qwen 3.5 loaded successfully
- The llama.cpp server is running properly
- Your SSH port forwarding is working
- The endpoint is fully compatible with OpenAI-style applications
At this point, you can integrate Qwen 3.5 into any local tool, agent workflow, or application that already supports OpenAI API format.
6. Building a Text UI Stock Screener with Llama.cpp WebUI
Llama.cpp includes a built-in WebUI styled like ChatGPT, which you can use to chat directly with the model in your browser. It's perfect for quick testing, iterating, and generating code without writing any client scripts first.
Since we've already set up SSH port forwarding, you can open the WebUI on your local machine and it'll feel like the server is running on your laptop.
By default, the WebUI is available at:
http://127.0.0.1:8080If the page loads, it confirms two things: your SSH tunnel is working correctly and the Qwen 3.5 server is accessible locally while still running privately on the GPU VM.
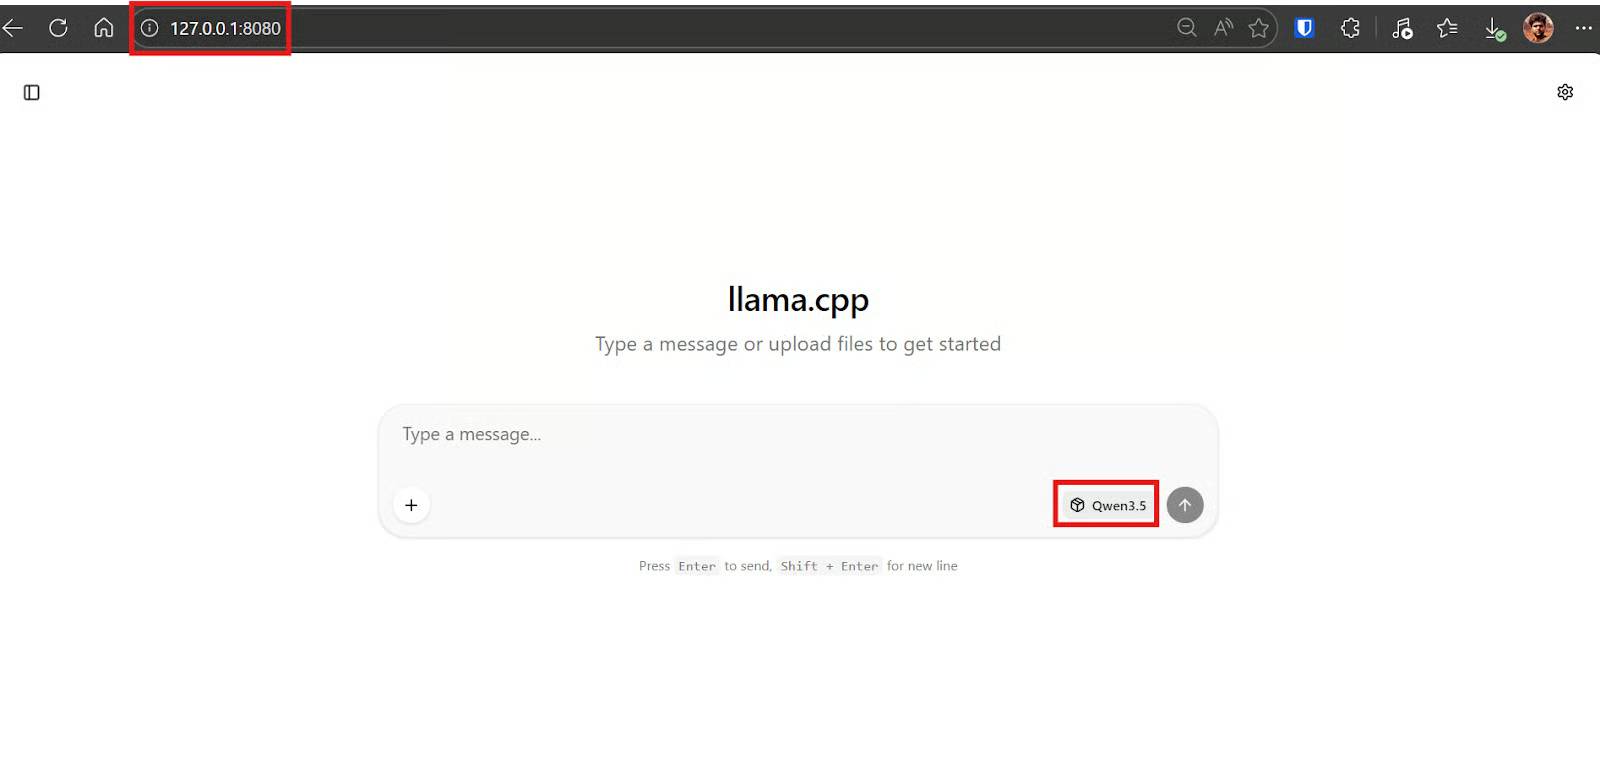
Once you're in the WebUI, paste this prompt. The goal is to get the model to generate both Python code and brief usage instructions.
Build a simple Python text-based user interface (TUI) application called "Stock Screener Trainer" that runs via `python app.py` using the rich library (not a web interface). The app lets me input a list of stock tickers, select a mode (growth/value/dividend), and risk level (low/medium/high), fetch public fundamental metrics for each ticker from a free source, display live loading status, then create a beautiful table and a "Top 5 by My Scoring Rules" section with a clear disclaimer "for educational purposes only, not financial advice", and save all results to `results.csv`.Within seconds, Qwen 3.5 will generate an `app.py` file and usually a brief explanation of how to run it.
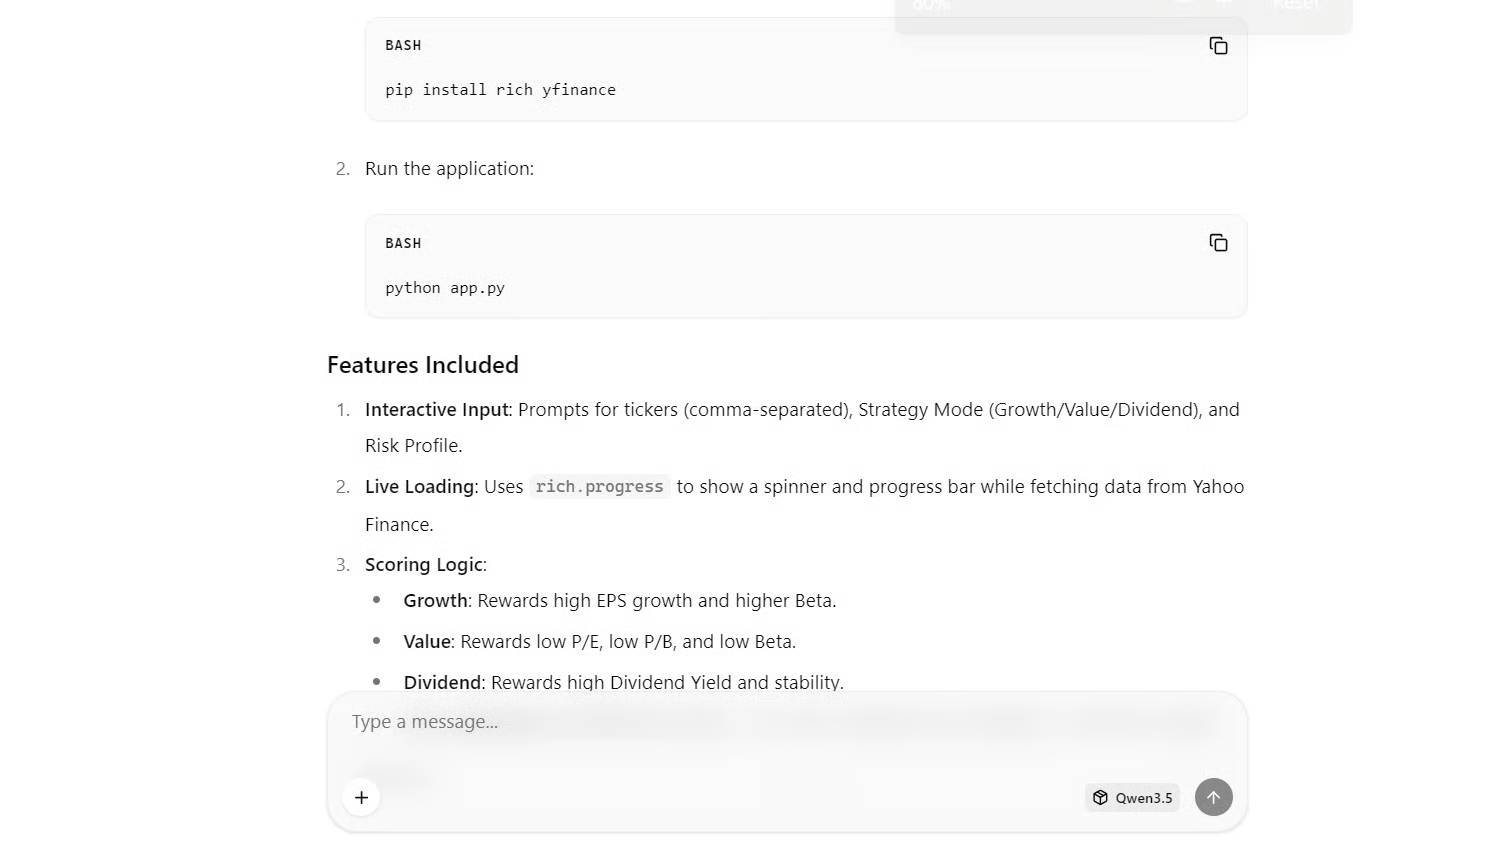
Now switch to your local terminal. Install the required libraries for the generated application:
pip install rich yfinanceThis installs:
- rich for text-based UI layout, tables, prompts, and progress indicators
- yfinance for fetching free, public stock metrics
Create a file named app.py, paste the model-generated code, and run it:
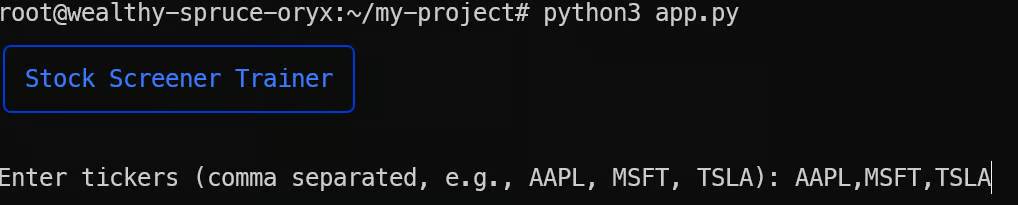
python3 app.pyOnce you run the script, you'll see the text-based UI launch correctly in your terminal. The app will prompt you to input the stock tickers you want to analyze, along with your preferred screening mode and risk level.
For example, the article author tested it with three popular stocks.
After a brief loading period, the tool returns a complete table of stock metrics, highlights results based on scoring rules, and saves everything to results.csv.
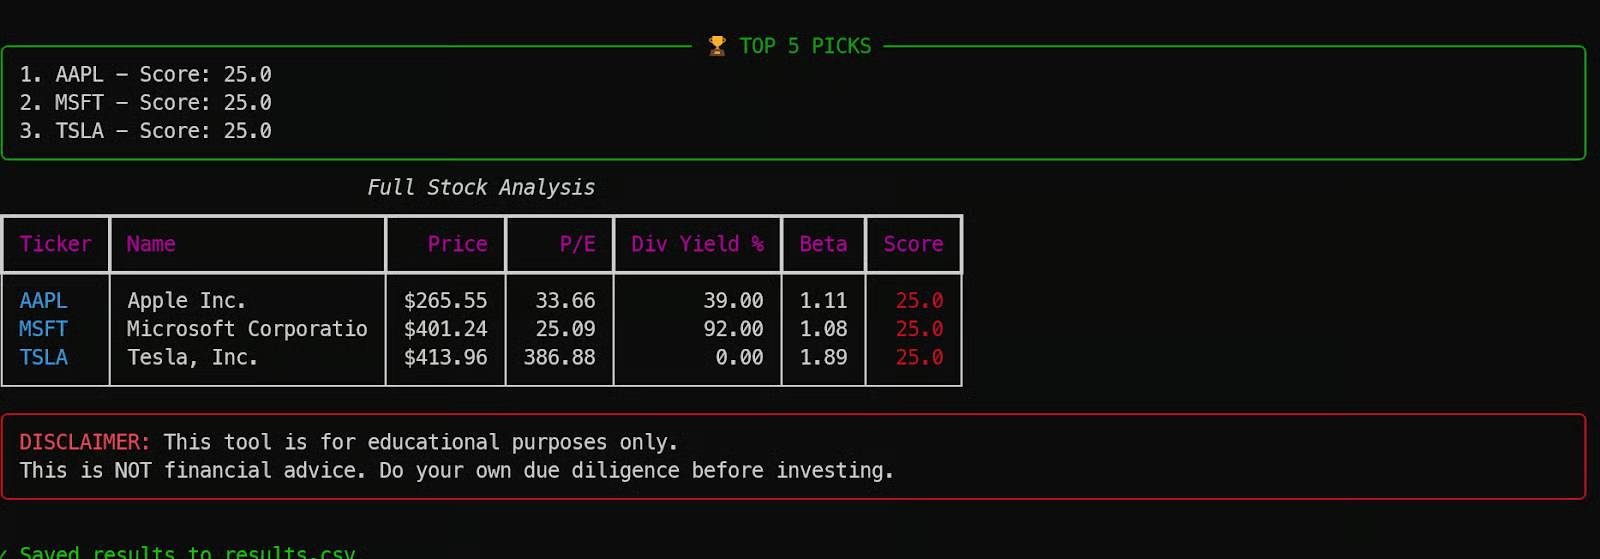
This is a fantastic example of how Qwen 3.5 can generate a fully-working application in a single shot, using just a 4-bit quantized model endpoint and a straightforward prompt.
Conclusion
Running Qwen 3.5 locally is a powerful way to access a massive language model while keeping everything private and completely under your control. In this guide, the model was hosted on a single H200 GPU VM, accessed securely from your local machine using SSH port forwarding, and served through an OpenAI-compatible endpoint (llama.cpp).
That said, there are a few practical limitations worth noting. Since everything depends on an active SSH tunnel, your connection needs to stay stable. If your internet drops or the session disconnects, you'll lose access to the local port and typically need to reconnect and restart parts of the workflow.
Another common gotcha is building llama.cpp correctly. If you don't specify the right CUDA architecture flags for your GPU, compilation takes longer and might not be fully optimized for your hardware. Getting the architecture right from the start makes a noticeable difference in build time and performance.
Finally, while the MXFP4_MOE 4-bit quantization is fantastic for running large models efficiently, it's not always ideal for deep agentic reasoning tasks. During testing with tools like Qwen Code CLI, Kilo Code CLI, and OpenCode, the model struggled with deeper reasoning and frequently failed in long code-generation loops—sometimes even causing GPU instability.
Higher-precision quantizations or smaller reasoning-focused models often perform more reliably for agent-based programming workflows.
Qwen 3.5 FAQs
What does the "397B-A17B" notation in the Qwen 3.5 model name mean?
This refers to the model's sparse Mixture-of-Experts (MoE) architecture. The model has 397 billion total parameters, but only activates 17 billion parameters (A17B) per token during inference. This design lets you tap into the reasoning power of a top-tier model without needing a supercomputer with multiple GPUs just to process a single prompt.
Can you run the Qwen 3.5 397B model on a regular desktop or Mac?
Running the full, uncompressed model requires enterprise-grade hardware, but quantization techniques make it feasible on high-end consumer machines. The 4-bit quantized version (like MXFP4 or GGUF format) needs about 214–256GB of total memory. That means you could run it on a Mac Studio with 256GB unified memory or a PC with a 24GB GPU plus substantial system RAM using llama.cpp's MoE offloading. If your hardware is lower-spec, Alibaba also offers lighter variants in the Qwen 3.5 lineup, such as the 35B-A3B version.
What makes Qwen 3.5 better than previous Qwen versions for local deployment?
Unlike earlier generations that treated text and images separately, Qwen 3.5 is a unified language-vision model trained end-to-end from the start on text, images, UI screenshots, and video. It also uses a new hybrid architecture (combining Gated Delta Networks with MoE), delivering significant decoding speedups and handling massive context windows (up to 256K tokens in native mode) far more efficiently than before.
Why is your locally-running Qwen 3.5 model slower than expected with llama.cpp?
If throughput (tokens per second) is too slow, the issue usually stems from build configuration or memory bottlenecks. First, make sure you built llama.cpp with the correct CUDA architecture flags for your GPU (e.g., -DCMAKE_CUDA_ARCHITECTURES="90a" for H200). Second, check memory usage. If your combined VRAM and RAM can't hold the quantized model, llama.cpp spills to SSD (page memory), causing severe inference slowdowns.
Description: Deploy Alibaba's Qwen 3.5 model locally using llama.cpp on a single GPU with step-by-step instructions and OpenAI API compatibility.
Related Articles
- Generate Images Directly in Google Sheets Using Gemini
- Why Claude Cowork Is Being Hailed as 2026's Biggest AI Breakthrough
- Why You Should Downgrade from Copilot and Switch to Claude for Office Work
- Four Missing Features That Would Make NotebookLM Even Better
- The Best AI Programming Tools You Should Know About in 2024

No Comment to " Running Qwen 3.5 Locally on a Single GPU: Complete Setup Guide "