Diffbot Explained: How AI Powers Intelligent Web Data Extraction
Diffbot specializes in machine learning algorithms and computer vision technology, offering public APIs that automatically pull data from web pages to build knowledge databases. What's interesting here is how the platform transforms messy, unstructured web content into clean, usable information at scale.
What Exactly Is Diffbot?
Diffbot is an AI-powered platform for web data extraction and analysis. It converts unstructured web content into organized, actionable data. Using machine learning and computer vision, the platform automates information gathering from websites, letting businesses access and analyze data without manual collection. Its comprehensive Knowledge Graph system consolidates information about organizations, products, and articles—powering smarter decisions across industries.
The Diffbot Story
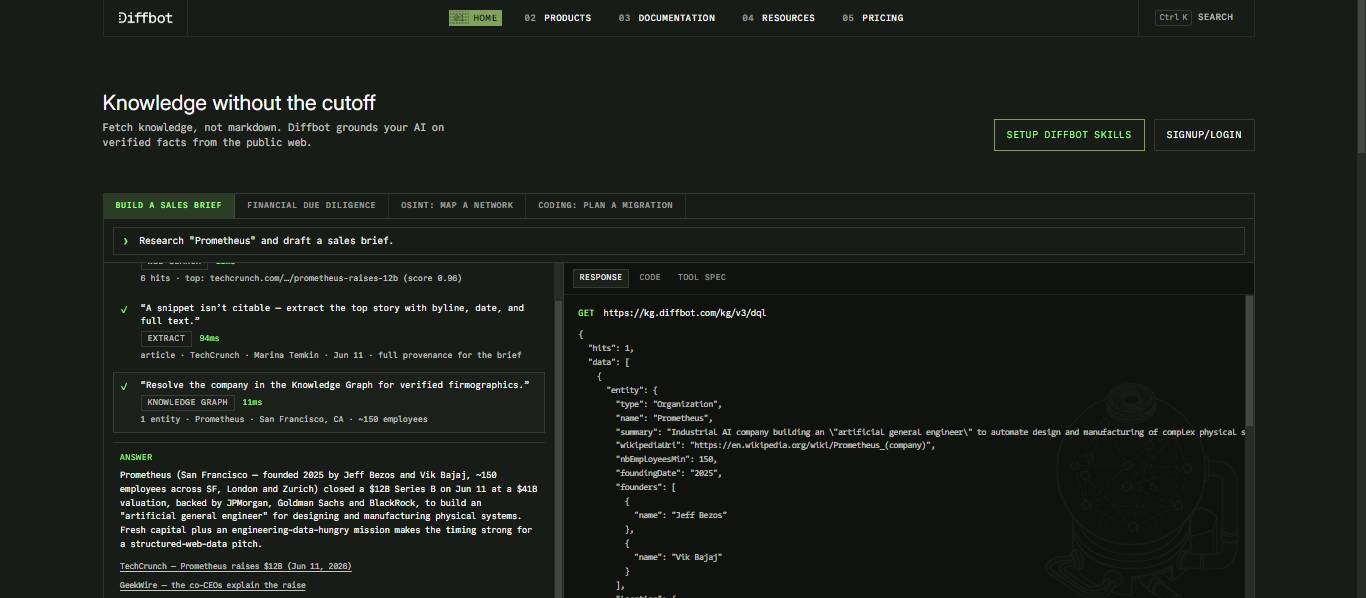
The company gained attention by applying computer vision directly to web pages, visually analyzing each page to identify important elements and return them in structured format.
In 2015, Diffbot announced it was building an automated Knowledge Graph by harvesting web information and using automated extraction to construct a massive database of structured web data.
By 2019, the company released its Knowledge Graph. Since then, it's ballooned to encompass over two billion entities—corporations, people, articles, products, discussions, and more—plus ten trillion interconnected events.
Key Features
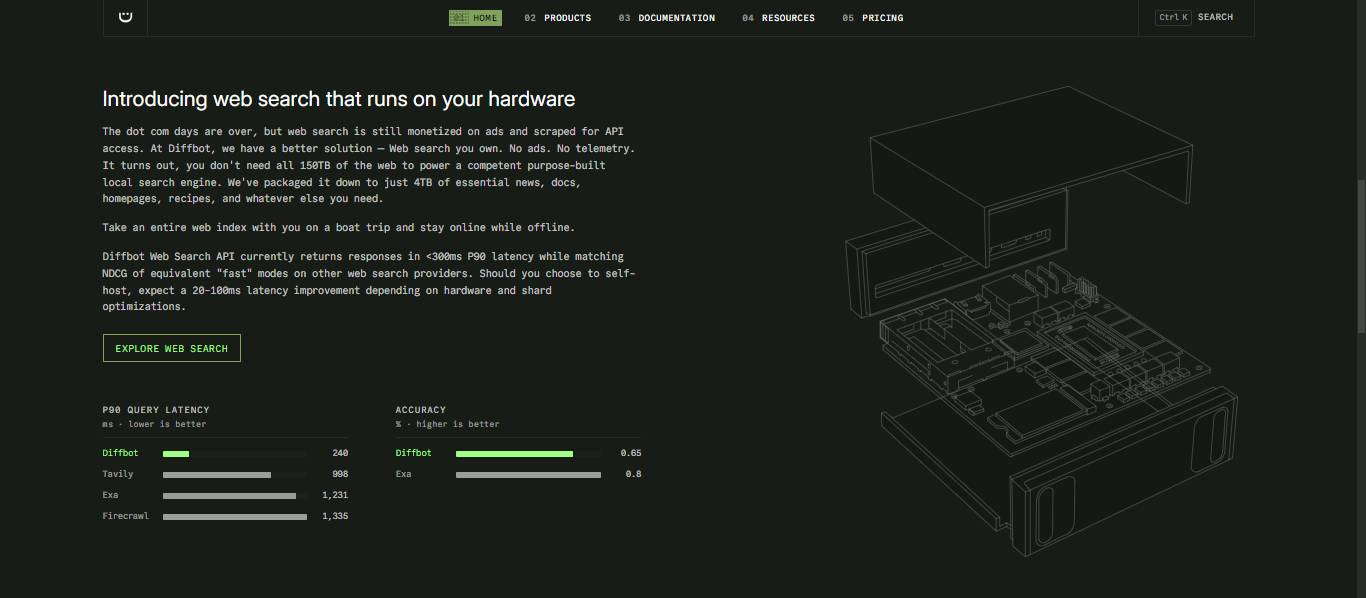
Diffbot's products let developers analyze homepages and article pages, pulling out critical information while filtering out noise. The platform focuses on what matters to your use case.
In August 2012, the company released its Page Classifier API, which automatically sorts webpages into specific categories. As part of this rollout, Diffbot analyzed 750,000 pages shared on Twitter, discovering that images dominated social sharing, followed by articles and videos.
September 2020 brought a natural language processing API that automatically builds Knowledge Graphs from raw text. The company has attracted notable investors including Andy Bechtolsheim and Sky Dayton, raising $2 million in funding (May 2012). Major customers include Adobe, AOL, Cisco, DuckDuckGo, eBay, Instapaper, Microsoft, Onswipe, and Springpad.
Here's what makes Diffbot powerful:
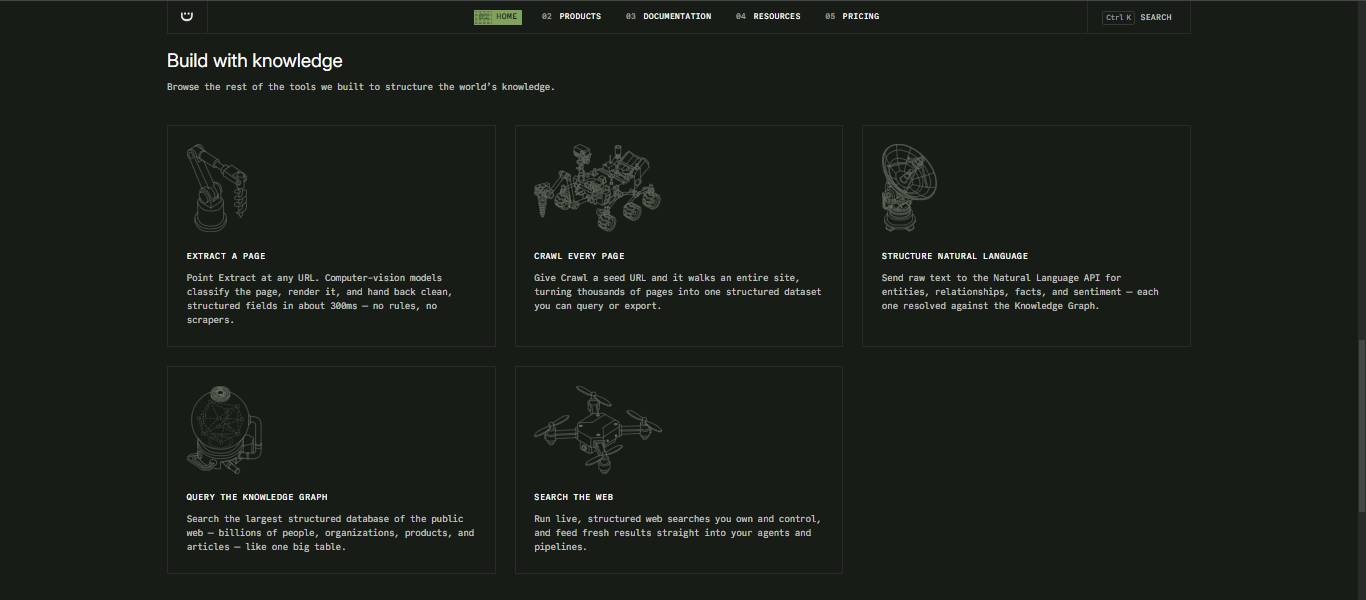
- Automated Data Extraction: Pull structured data from any webpage using AI, computer vision, and machine learning.
- Knowledge Graph: Access a massive database of interconnected entities—over 246 million organizations and 1.6 billion articles.
- Crawlbot: Harvest data across entire websites, whether single pages or complete domains.
- Natural Language Processing: Analyze text to extract entities, relationships, and sentiment automatically.
- API Access: Integrate smoothly with existing systems and workflows through well-documented APIs.
Pricing Breakdown
- Free Plan: $0/month. Includes 10,000 credits, 5 calls per minute, and dashboard access.
- Startup Plan: $299/month. Offers 250,000 credits, 5 calls per second, and API access.
- Plus Plan: $899/month. Features 1,000,000 credits, 25 calls per second, plus extras like Crawl functionality.
- Enterprise Plan: Custom pricing with tailored features and support.
Pros and Cons
Advantages
- Automates complex web data extraction workflows.
- Grants access to an extensive, comprehensive knowledge repository.
- Offers scalable solutions for businesses of any size.
- Integrates seamlessly with existing systems via API.
Drawbacks
- Premium tiers can be expensive for smaller companies. The real concern is budget creep as data needs grow.
- Mastering advanced features takes time and effort.
- The credit-based system requires careful monitoring to avoid surprise overage charges.
See It In Action
Description: Discover how Diffbot uses AI and computer vision to automatically extract and analyze structured data from websites. Learn features, pricing, and real
Related Articles
- Microsoft Copilot vs ChatGPT: Which AI Assistant Should You Actually Use?
- Master ElevenLabs v3: Creating Emotionally Expressive AI Voices
- What Is Google's Nano Banana 2? Complete Guide & Usage Tips
- Gemini Now Lets You Create Images by Speaking—No Typing Required
- Bases: Obsidian's New Plugin Finally Closes the Gap Notion Left Behind

No Comment to " Diffbot Explained: How AI Powers Intelligent Web Data Extraction "